
Diagnostic assessment
A NAS SSD Has Different Constraints From a Workstation SSD
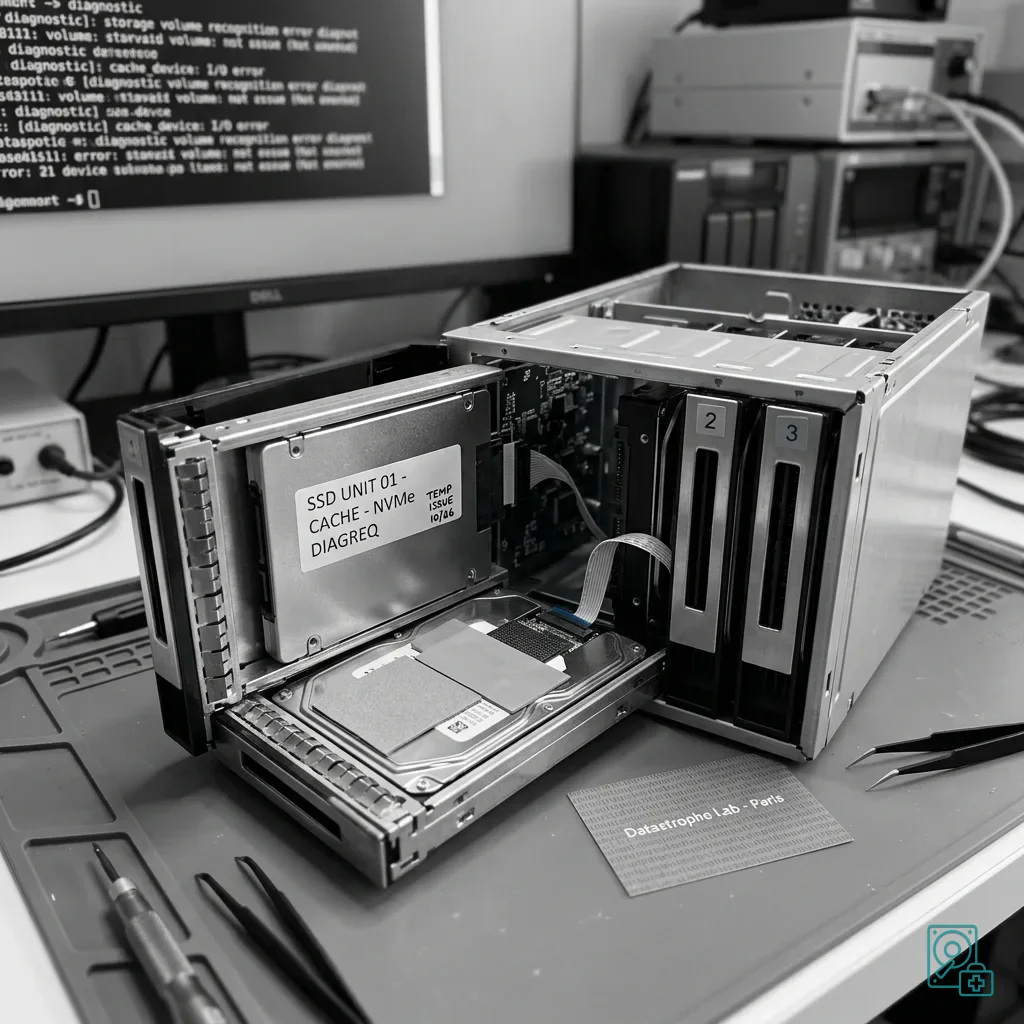
An SSD installed in a NAS often works in a denser environment than one in a personal computer. It may hold the main volume, act as a read cache or write cache, or store virtual machines. Each of these uses places sustained demands on the controller and memory cells.
Heat is a warning that should be taken seriously, but it does not explain the fault on its own. Poor bay ventilation, an SSD unsuited to the workload, continuous writes, unstable firmware, a RAID rebuild or a saturated cache can all be involved.
The risk to data depends on the SSD's role. A read cache has different implications from a write cache. A primary all-flash volume also has different priorities from a cache attached to a RAID made up of hard drives.
RAID system data recovery covers NAS and RAID cases more broadly. This article isolates the SSD scenario because flash media require a different approach from mechanical disks.
Do not replace the SSD or rebuild the volume before its function is understood. An operation that appears sensible from a hardware perspective may alter volume consistency or discard data still waiting in the cache.
The installation context matters too. An SSD positioned near a power supply, inside a compact enclosure or behind a poorly ventilated fascia can reach high temperatures before the user notices a problem. Preserve and review the NAS alerts before intervening.
Diagnostic assessment
An SSD Cache Can Complicate Recovery
An SSD cache can speed up NAS access, but it also adds another layer. With write caching, some data may pass through the SSD before it is confirmed on the main volume. If a failure occurs, consistency depends on exactly how that cache was configured.
Identify the SSD's precise role: read cache, write cache, storage, tiering, system volume or virtual-machine datastore. NAS logs, configuration details and the physical order of the disks may all be decisive.
Removing the cache, resetting it or starting a rebuild can erase useful information. Even when the NAS offers an automatic repair, first establish what it will write and which volume it will change.
Why business NAS recovery is often underestimated explains why NAS appliances are too readily treated as simple enclosures. An SSD cache makes that shortcut still more hazardous.
Recovery must take every layer into account: the SSD, primary disks, RAID, snapshots, shares, virtual machines and backups. Looking only at the component that is running hot may leave the real data state unresolved.
Diagnostic assessment
Heat, Endurance and Continuous Writes Accumulate
An SSD has no moving parts, but it is not immune to failure. Continuous writes, heat, lack of free space and some cache workloads can wear or destabilise the device. A NAS that journals, synchronises or hosts virtual machines may write far more data than an ordinary workstation.
The warning signs are concrete: slow access, a disabled cache, a degraded volume, SMART errors, high temperature, a missing SSD, an unexpected rebuild, blocked snapshots or inconsistent files. They need to be interpreted together.
Heat may affect several components at once. When airflow through the bay is poor, the SSD, neighbouring disks and power supply can all be exposed. Replacing a single part will not necessarily resolve the wider fault.
Why NVMe SSD recovery is difficult describes controller, TRIM and flash-memory constraints. In a NAS, those limits interact with the RAID and cache configuration.
Avoid prolonged tests on an unstable SSD. An intensive scan, rebuild or uncontrolled copy can consume the last useful reads and obscure the sequence in which the failure developed.
Diagnostic assessment
Preserve the NAS Before Any Rebuild
Before intervening, retain the NAS configuration: model, software version, SSD role, disk order, RAID level, logs, alerts and every operation already attempted. These details prevent a reconstruction based on assumptions.
Wait if the interface offers to remove the cache or reintegrate an SSD. A quick confirmation may change the main volume. The priority is to establish whether the cache holds unique pending data or only copies used to accelerate reads.
Check backups on separate healthy storage. Restoring directly to the affected NAS can overwrite evidence needed for diagnosis. Operational recovery must remain separate from recovery of the lost data.
RAID servers under load and the risks of rebuilding reinforces this caution. Whenever several storage layers interact, the additional workload can make the incident worse.
A priority data list is essential. Shared folders, databases, photographs, video, workstation backups and virtual machines do not require the same checks. Recovery should target the content that has real operational value.
Diagnostic assessment
Prevent Repeat NAS SSD Failures
After an incident, prevention starts with the configuration. Confirm that the selected SSD suits its workload, airflow is adequate, temperature alerts are monitored and backups are tested.
The team administering the NAS should understand the cache. Knowing whether it is configured for reads or writes changes the correct response to a fault. A written procedure prevents a hurried click on a repair suggested by the interface.
Snapshots and backups must remain distinct. A local snapshot on the same NAS does not protect against enclosure-wide failure, corruption or a rebuilding error. It can help in some cases, but it is not a substitute for a healthy independent copy.
Datastrophe can assess a NAS with an SSD cache, primary SSD storage or a hybrid volume. The work aims to preserve the existing state, establish the SSD's role and return useful files without confusing a successful NAS restart with successful data recovery.
A NAS fitted with SSDs may be fast, but it remains a complex storage system. Its protection depends less on the media type than on configuration, backups and the decisions made when an incident occurs.
When the NAS hosts cameras, virtual machines or workstation backups, writes may be continuous. That workload must inform both SSD selection and the recovery plan because it affects wear as well as heat.
Diagnostic assessment
Primary Technical References And Limits
Reference scope — SSD overheating cache data recovery: For NAS SSD overheating cache data recovery, the primary references used are europe.kioxia.com. Physical evidence — SSD overheating cache data recovery: They define the relevant preservation, storage or validation concepts, but they cannot establish the exact physical condition, controller state, key availability or business consistency of the device received. Controller evidence — SSD overheating cache data recovery: Those points require measurements on the original set and verification on copies.
Diagnostic assessment
Arrange A Controlled Assessment
Complete set — SSD overheating cache data recovery: For a technical examination of NAS SSD overheating cache data recovery, provide the complete device or storage set, its associated power and interface parts, the symptom timeline and the priority records. Incident history — SSD overheating cache data recovery: Keep member order, labels and authorised credentials separate from the parcel paperwork; do not restart the source merely to obtain a new screenshot.
Laboratory responsibility — SSD overheating cache data recovery: Datastrophe performs the diagnosis, integrity checks and recovery directly in its own laboratory with its own team. Free assessment — SSD overheating cache data recovery: Diagnosis and the quotation are free. Transport boundary — SSD overheating cache data recovery: Private collection and return is included; the carrier moves only the sealed parcel and neither accesses nor processes its data.
Controlled list — SSD overheating cache data recovery: Before any payment, the client receives the proposed price and a checked list. Verification classes — SSD overheating cache data recovery: Each item is classified, in order, as recoverable_verified, partial, detected_unverified or unrecoverable. Payment trigger — SSD overheating cache data recovery: Only recoverable_verified items whose contents were checked and found usable are presented as recoverable. No-result rule — SSD overheating cache data recovery: Payment is due only after the client accepts both the list and the price.
No-result rule — SSD overheating cache data recovery: If no usable data is verified, recovery fails, or the client declines the list or price, no standard fee is payable. Rare-part exception — SSD overheating cache data recovery: The only exception is a rare, costly and non-refundable part, which may be ordered only after a separate, explicit and priced proposal has been accepted.