
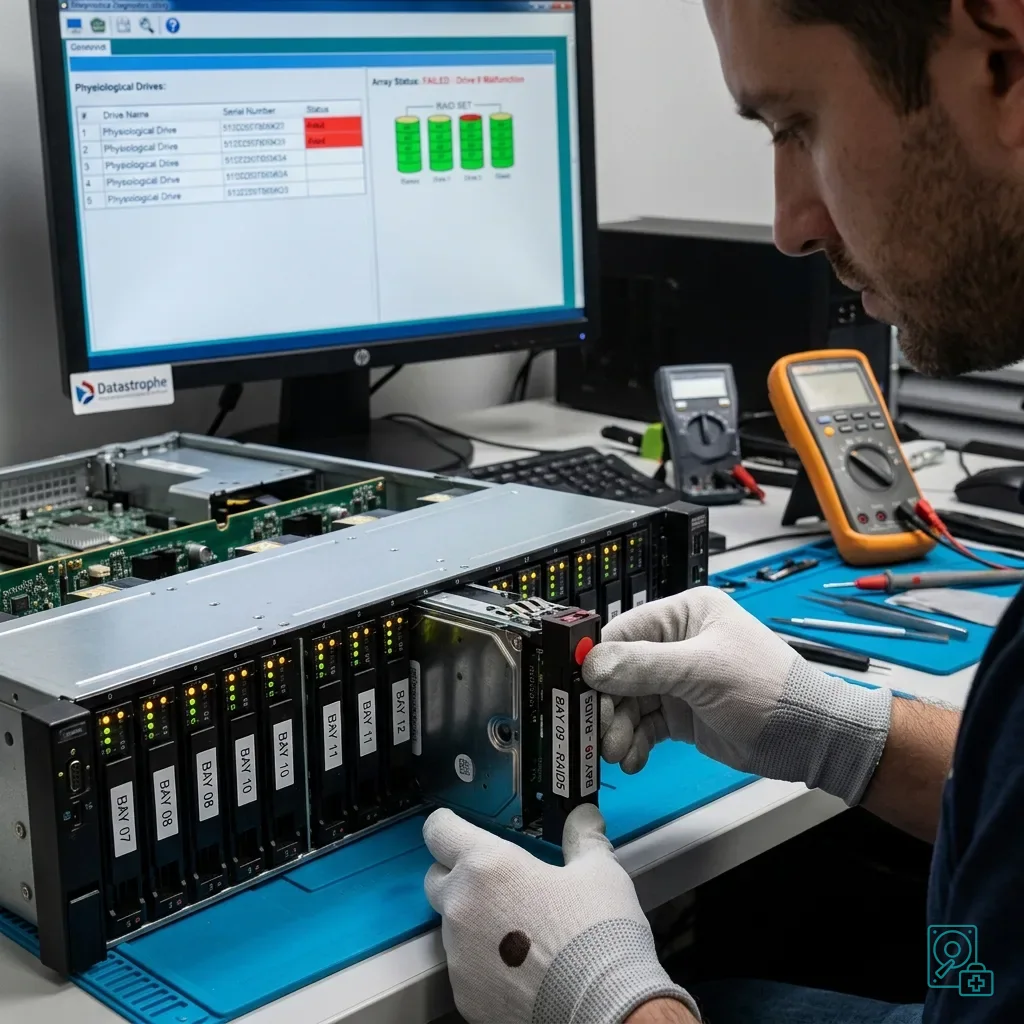
Diagnostic evaluation
Measure the Workload Before Rebuilding Server RAID
A server RAID may look stable under ordinary demand, then change sharply when a member fails and reconstruction begins. Surviving disks read more, the controller writes continuously, applications stay active, and backup traffic may add another full workload.
This combination explains why an array can fail under load. The replacement disk is rarely the whole story, as reconstruction often exposes existing weak sectors, heat, marginal power, an intermittent backplane, controller errors or a nearly full volume.
Early signs can be deceptive. The server still runs, but response times rise, I/O errors enter the logs, rebuild progress stalls or another member leaves the group; each should be treated as a serious warning rather than ordinary slowdown.
The RAID data recovery service describes the service process. This article focuses on the vulnerable period in which reconstruction and active server workload compete for the same storage.
Preserve the state before adding another operation. A forced rebuild, restore to the same location or undocumented restart can change member metadata and make the later recovery path less certain.
Schedule matters alongside throughput. A rebuild during financial close, mass synchronization, or a backup window faces a different I/O profile than one during a quiet maintenance period.
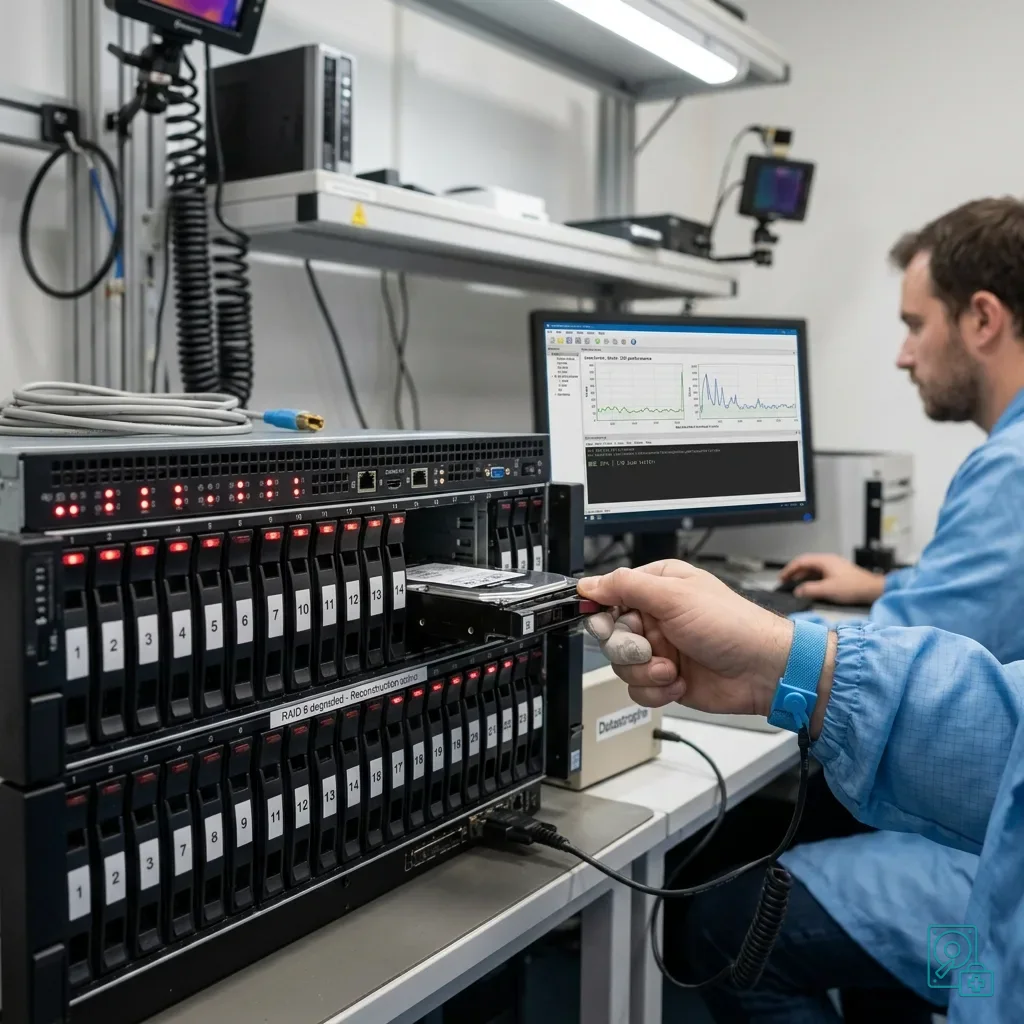
Diagnostic evaluation
Account for Every Read and Write During Reconstruction
Reconstruction is not neutral background activity. It reads source members, calculates replacement blocks, and fills a target while databases, scans, virtual machines, and backup jobs continue using the same disks and controller.
If another member already has weak sectors, sustained reading can push it beyond recovery. The server can move from a degraded but available volume to an incoherent or inaccessible one, particularly where disks share age and operating conditions.
Assess member health before allowing progress to continue unchecked. SMART, RAID-controller, operating-system and hypervisor logs can indicate whether risk is confined to one disk or extends across the enclosure.
The guide to repeated server-disk failure assessment adds context. Closely spaced faults and difficult rebuilds should be treated as a system problem, not merely a queue of members to replace.
For some sets, reducing load and imaging the members before reconstruction is the safer sequence. RAID level, number of unstable disks, data value, and outage constraints should drive that decision.
Diagnostic evaluation
Test Shared Controller, Backplane, Power, and Cooling Paths
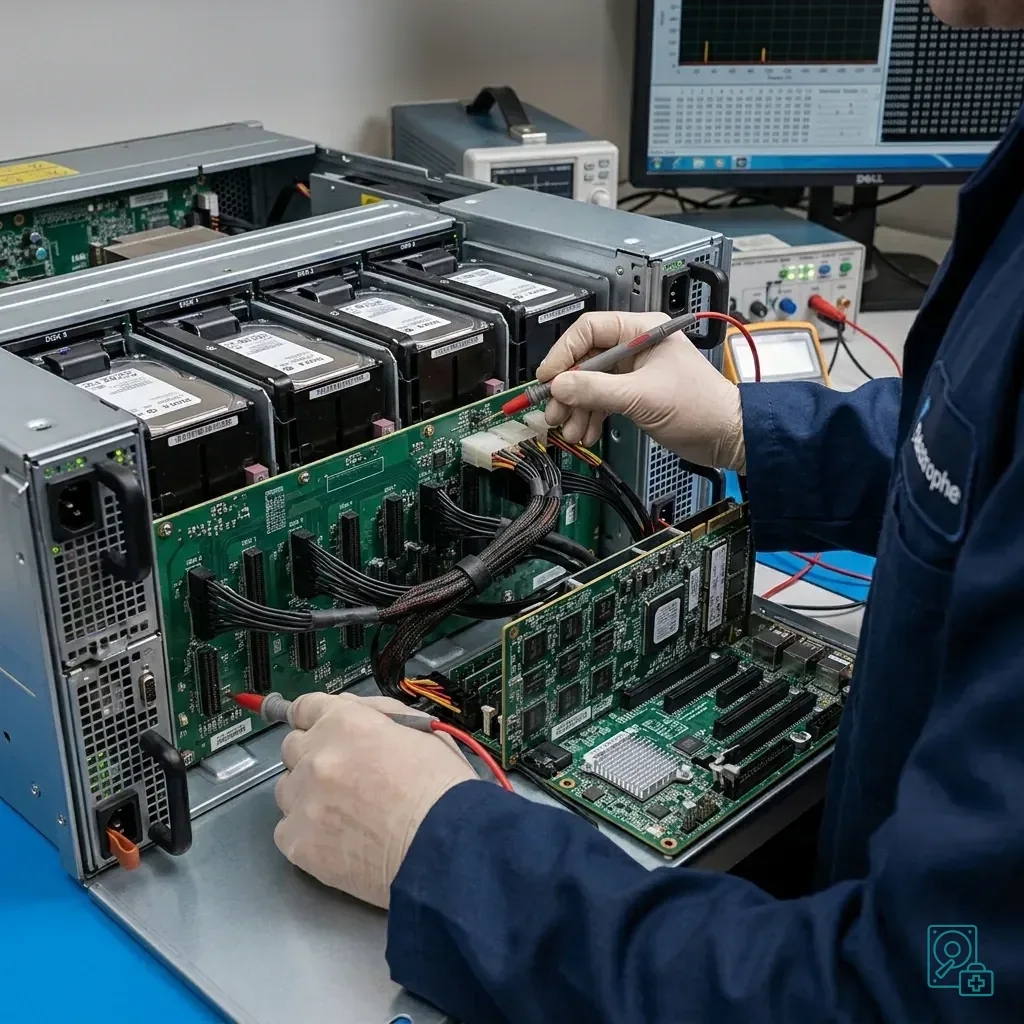
The array also depends on shared infrastructure. A controller, backplane, cable, power rail, or cooling path can produce errors on several members, so replacing one disk cannot solve every apparent disk failure.
Backplanes are frequently overlooked. An intermittent bay can break contact or generate errors that resemble media failure, and this instability becomes particularly dangerous when reconstruction repeatedly traverses every member.
Heat and power deserve the same attention. A dense rack, restricted airflow or heavily loaded supply may multiply faults during peak activity, causing failure at the exact time the RAID demands its greatest sustained performance.
The article on RAID redundancy and its limits reinforces an essential point: redundancy is not backup and cannot protect against a common cause, human error or an incorrectly started rebuild.
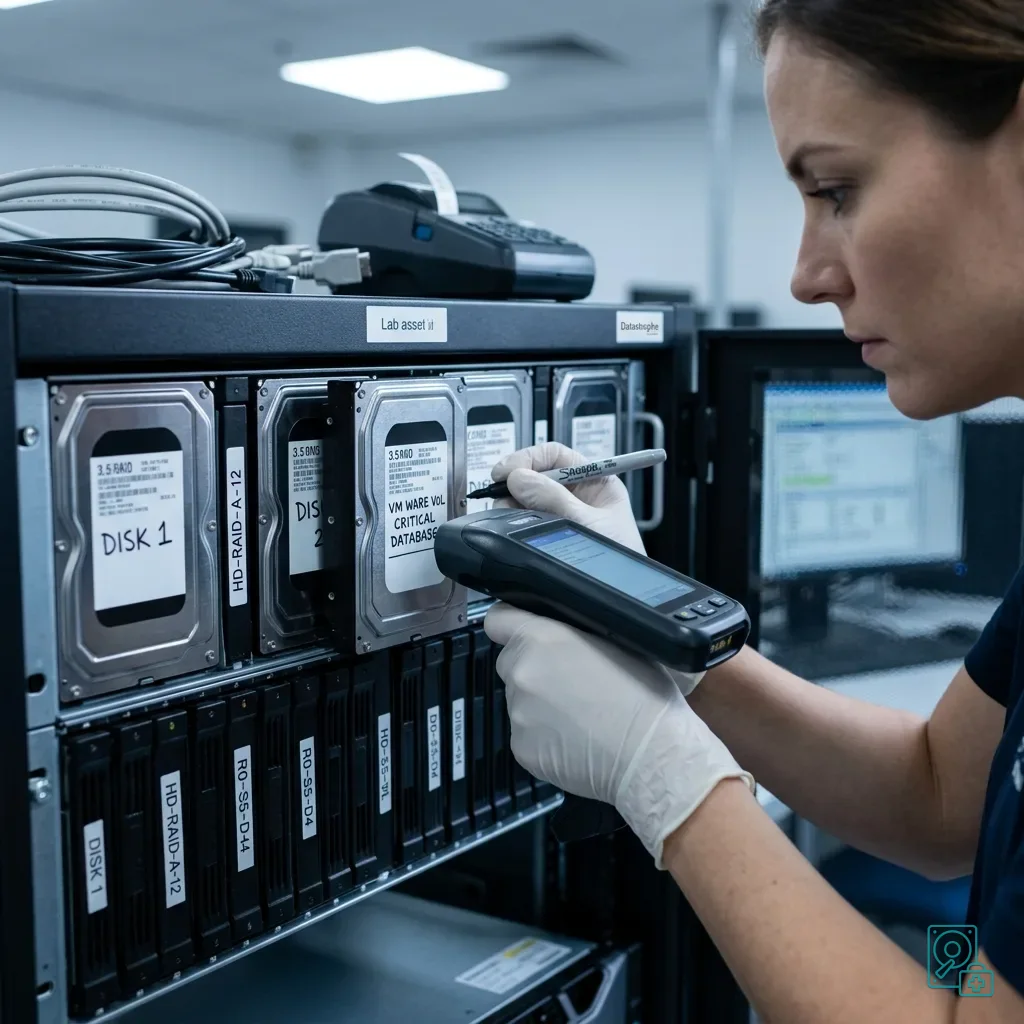
Evaluate both hardware and logical layers, including member order, array records, logs, and replacement history. Shared-component evidence may explain why several disks reported trouble together.
Diagnostic evaluation
Rank Business Data Before Restoring Availability
Rank the server's contents in operational terms before broad work begins. Databases, virtual machines, customer folders, email, production applications, and archives have different urgency and acceptance requirements.
Service can sometimes resume from a separate backup or copy while original members remain available for examination. Restoring into the wrong destination or resetting the group can erase exactly the evidence still needed.
Record every prior attempt: replaced disk and bay, rebuild start, percentage reached, displayed messages, restarts and backup jobs triggered. This chronology prevents the same risky operation being repeated under a different name.
The article on why critical server data is lost examines business priorities. On a busy RAID, that ranking helps choose among rapid failover, technical acquisition and controlled reconstruction.
Do not call the volume healthy at the first successful mount. Validate priority files, databases, and virtual machines before concluding that service restoration also resolved the data incident.
Diagnostic evaluation
Run a Controlled Intervention With Acceptance Checks
Prepare server and controller models, RAID level, member count and order, replaced disks, alerts, logs, and priority files. Complete configuration facts reduce guesswork while source disks remain fragile.
Do not mix members or test them individually without a traceable record. Reversal, initialization or forced import can modify metadata required to assemble the logical volume later.
If partial server availability is mandatory, make that constraint explicit. Some cases permit separate continuity arrangements while protecting the source set; in others, a controlled shutdown presents the lowest data risk.
Datastrophe can assess a loaded server RAID with data value taking precedence over immediate hardware restart. The aim is to separate member failure, shared cause, logical corruption and the realistic limits of recovery.
Keep prevention straightforward after the incident: tested backups, acted-upon alerts, documented RAID configuration, adequate cooling and a known rebuild procedure. Together they prevent one component fault from becoming a full service crisis.
When the array hosts virtual machines, include datastore, VM files, snapshots, and guest-level application checks in acceptance. Controller completion cannot prove a guest remained consistent through interrupted writes.
Diagnostic evaluation
Primary Technical References And Limits
Reference scope — RAID rebuild under load risks: For server RAID rebuild under load risks, the primary references used are Linux MD administration guide. Physical evidence — RAID rebuild under load risks: They define the relevant preservation, storage or validation concepts, but they cannot establish the exact physical condition, controller state, key availability or business consistency of the device received. Controller evidence — RAID rebuild under load risks: Those points require measurements on the original set and verification on copies.
Diagnostic evaluation
Request A Controlled Evaluation
Complete set — RAID rebuild under load risks: For a technical evaluation of server RAID rebuild under load risks, provide the complete device or storage set, its associated power and interface parts, the symptom timeline and the priority files. Incident history — RAID rebuild under load risks: Keep member order, labels and authorized credentials separate from the parcel paperwork; do not restart the source merely to obtain a new screenshot.
Laboratory responsibility — RAID rebuild under load risks: Datastrophe performs the diagnosis, integrity checks and recovery directly in its own laboratory with its own team. Free assessment — RAID rebuild under load risks: Diagnosis and the quote are free. Transport boundary — RAID rebuild under load risks: Private round-trip shipping is included; the carrier moves only the sealed parcel and neither accesses nor processes its data.
Controlled list — RAID rebuild under load risks: Before any payment, the client receives the proposed price and a checked list. Verification classes — RAID rebuild under load risks: Each item is classified, in order, as recoverable_verified, partial, detected_unverified or unrecoverable. Payment trigger — RAID rebuild under load risks: Only recoverable_verified items whose contents were checked and found usable are presented as recoverable. No-result rule — RAID rebuild under load risks: Payment is due only after the client accepts both the list and the price.
No-result rule — RAID rebuild under load risks: If no usable data is verified, recovery fails, or the client declines the list or price, no standard fee is payable. Rare-part exception — RAID rebuild under load risks: The only exception is a rare, costly and non-refundable part, which may be ordered only after a separate, explicit and priced proposal has been accepted.